
Firecrawl: Web Data for Agents
About this video
If you write your own crawler: robots.txt, one queue per host and 304 Not Modified make the polite option the cheap one too.
Firecrawl is an open-source API that turns any web page into clean Markdown, ready for a language model. With scrape and crawl endpoints plus schema-guided JSON extraction, it gives your AI agent reliable web data. This guide covers its formats, how to self-host it with Docker and when it beats a scraper of your own.
Video transcript
- 0:01 First we fetch robots.txt and honour it:
- 0:05 disallowed paths are never requested.
- 0:07 One queue per host, two requests per second, with an honest User-Agent.
- 0:12 The first fetch downloads 142 KB and stores the validators with the document.
- 0:18 On the revisit, the request includes the stored validator and asks whether anything
- 0:23 changed.
- 0:24 If nothing changed, the server answers 304 Not Modified:
- 0:28 zero KB, nothing to parse again.
- 0:31 Wasted revisits drop from 375 to 59.
- 0:35 The polite choice and the cheap one are the same.
More videos
Explainer
How to Install SearXNG with Docker
One use for your own instance: an AI agent that finds its own sources by querying SearXNG, without paying per search.
Explainer
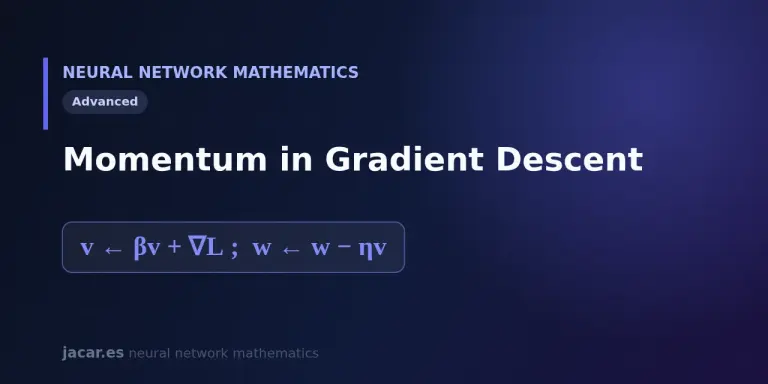
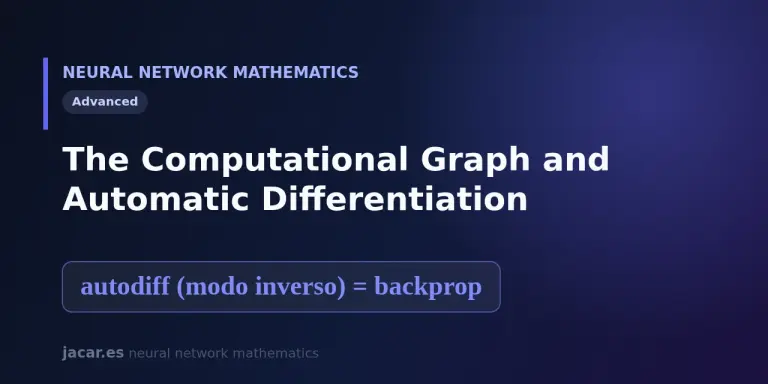
The Computational Graph and Automatic Differentiation
The computational graph and automatic differentiation, in action.
Explainer
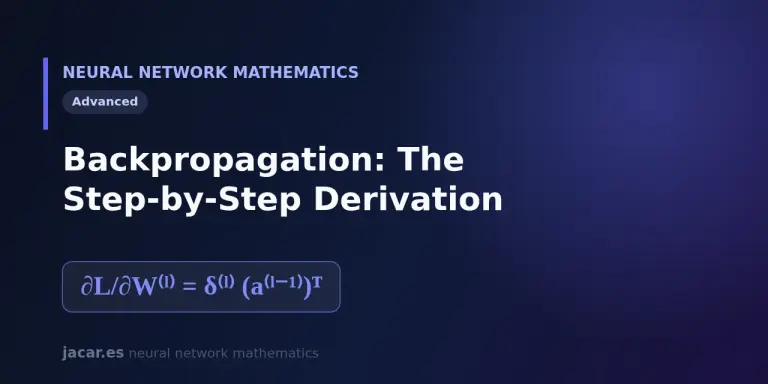
Backpropagation: The Step-by-Step Derivation
The backpropagation derivation, factor by factor with the chain rule.
Explainer
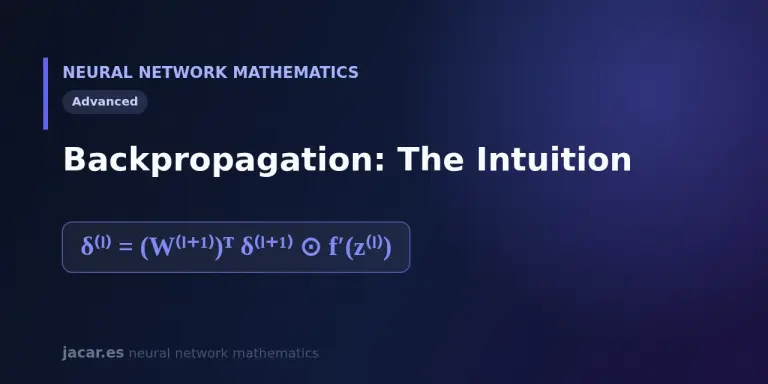
Backpropagation: The Intuition
The intuition of backpropagation: the error flows backward through the network.