On an arm64 CPU with no GPU, llama.cpp 0.5.0 served Qwen3-1.7B as a Q8_0 GGUF at 72.7 tokens/s per request and 236.9 tokens/s with 8 concurrent requests. vLLM 0.30 in BF16 reached 10.1 and 68.3 tokens/s and used 11.4 GiB of RAM against 7.0 GiB.
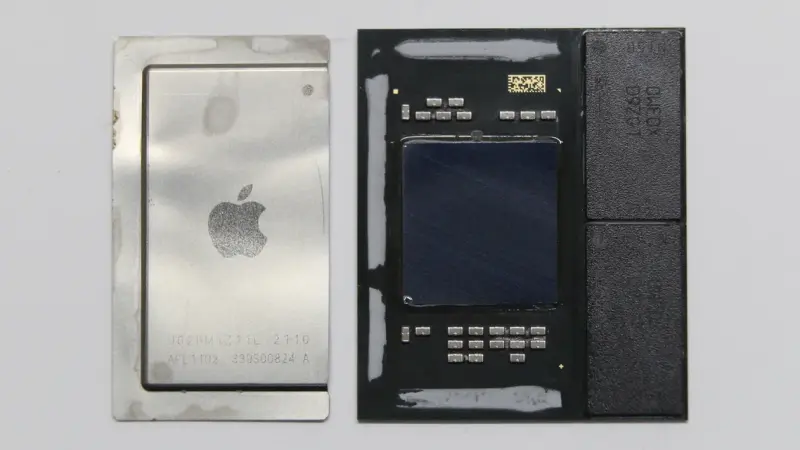
Without a GPU, on an 18-core arm64 CPU with llama.cpp v0.4.1, Maple-Preview generated 172.84 tokens/s on 6 threads: twice MiniCPM5-2B and 3.6 times Spark-X2.5-4B. The trade-off is 5.79 GiB of RAM and reasoning it cannot switch off. MiniCPM5 fits in 3.27 GiB and Spark writes the best Spanish. All three made facts up.
20 min66
We use first- and third-party cookies to analyze site traffic. You can accept them, reject them, or configure your choice.
Learn more about cookies
Cookie preferences
NecessaryEssential for the site to work. Always on.
AnalyticsHelp us understand how the site is used (Google Analytics).