Espresso is a Swift library that compiles MIL programs straight for the Neural Engine of Apple Silicon Macs through private APIs, without Core ML. On a 6-layer model on an M3 Max it generates 519 tokens per second against 152 for Core ML; with real models such as Qwen2.5, attention stays on the CPU.
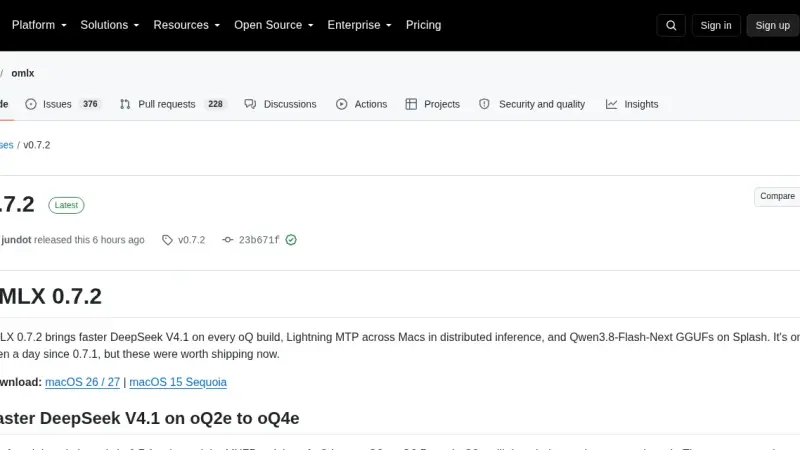
oMLX 0.7.2, released on 21 October 2026, one day after 0.7.1, speeds up DeepSeek V4.1 on the oQ2e to oQ4e quants, turns on Lightning MTP in multi-Mac clusters, runs Qwen3.8-Flash-Next GGUFs on Splash and stops re-prefilling the whole conversation on every Claude Code turn. You upgrade it from the app, Homebrew or source.
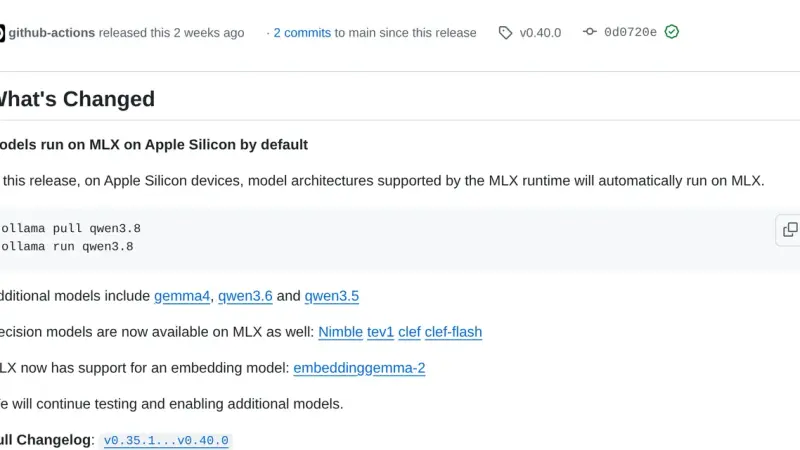
Since Ollama 0.40, released on 25 September 2026, models with a supported architecture run on MLX instead of llama.cpp on Apple Silicon Macs. Ollama picks the model variant at download time, and ollama ps shows in its RUNNER column which engine serves it. On Linux and Windows llama.cpp is still the default.
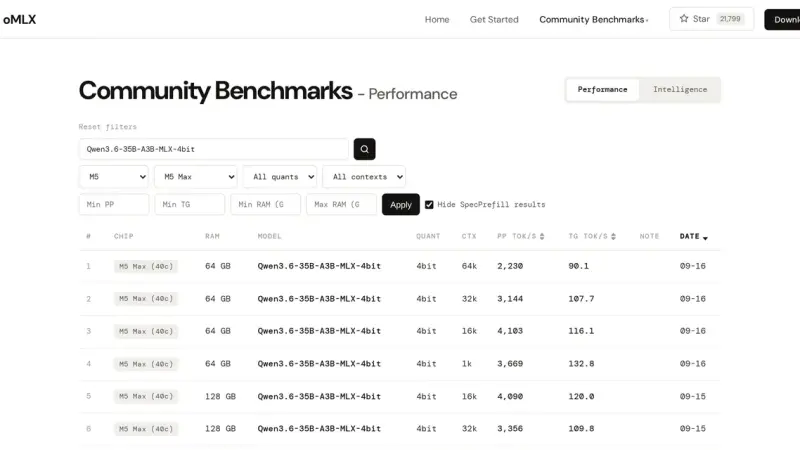
An oMLX tokens-per-second figure is only useful if it states the prompt length, the route, the cache state and the Mac's. On an M5 Max, Qwen3.8-27B's first token went from 1.12 to 65.5 seconds between a 1k and a 32k prompt. The default memory ceiling leaves 8 % of RAM for macOS, between 3 and 8 GB.
oMLX is a local inference server for Apple Silicon Macs that wraps Apple's MLX framework and exposes it through the OpenAI and Anthropic APIs. Since Ollama 0.40 all three major servers use MLX on a Mac, so what sets oMLX apart is memory: several models loaded with eviction and pinning, and an SSD KV cache that survives restarts.
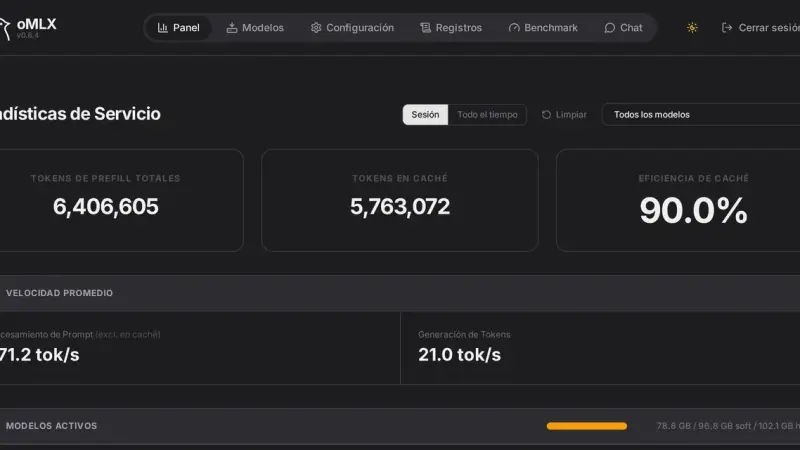
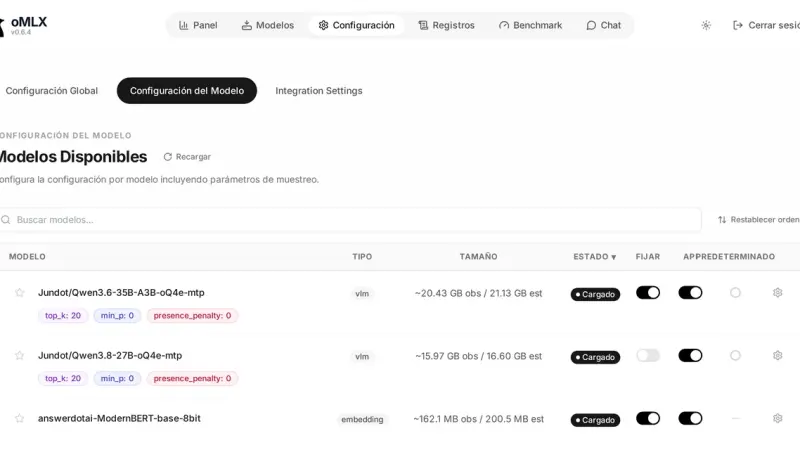
The oMLX panel lives at localhost:8000/admin and gathers monitoring, model loading and unloading, chat with history, a Hugging Face downloader, benchmarks and per-model settings. The command line covers the rest with four commands: serve, start, stop and launch, the last one for wiring up external clients.
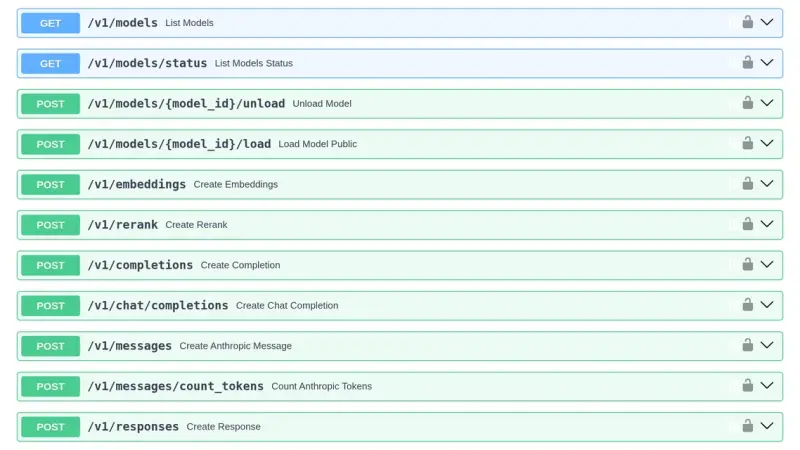
oMLX 0.7.2 listens on 127.0.0.1:8000 and serves OpenAI's API and Anthropic's Messages API on the same port. The key travels in Authorization: Bearer or in x-api-key and is mandatory as soon as the server listens beyond loopback. Errors come back in OpenAI's format, and the port changes with --port, OMLX_PORT or the server section of settings.json.
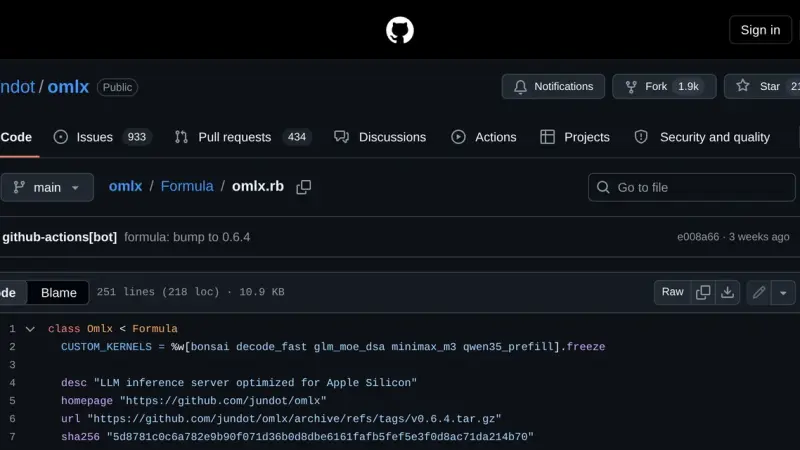
oMLX installs through Homebrew in two commands: first the tap for jundot's repository, then the formula. You end up with a launchd service that starts via omlx start, a log inside Homebrew's var directory and an upgrade path through brew upgrade. The current version is 0.6.4, released on 29 August 2026.
oMLX manages each model's lifecycle with four pieces: a downloader that pulls weights from Hugging Face, aliases that rename the model in the API, a TTL that unloads it after idle time, and a tiered KV cache that spills blocks to SSD when RAM fills up.
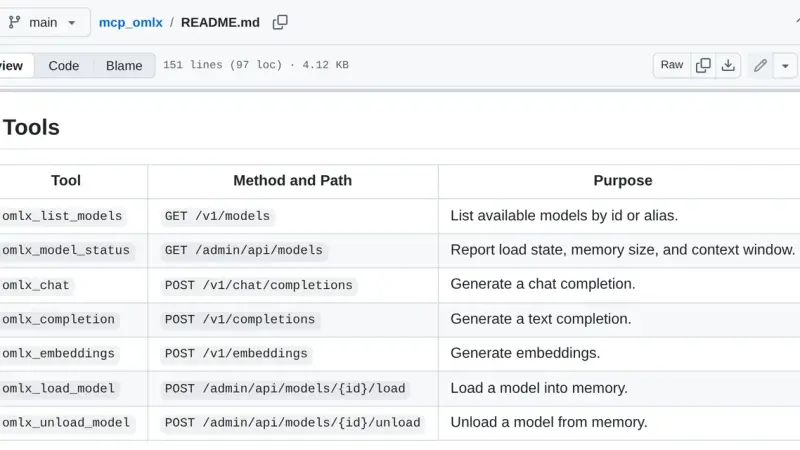
oMLX MCP is a bridge that exposes your local oMLX server as Model Context Protocol tools. The mcp_omlx package connects Claude Desktop to the models running on your Mac and gives you seven tools to list models, load and unload them from memory, and run inference without leaving the client.
Recipe for oMLX 0.6.4 on a Mac M5 Max with 128 GB: install, Claude Code and advanced settings with screenshots (Lightning MTP, VLM MTP and DFlash). Includes our own September 2026 benchmarks, with up to 1.88x more tokens per second.
100 must-have apps for your M5 Mac organised into 20 categories: browser, notes, terminal, IDE, containers, AI and more. Each pick with purpose, key features, plugins, pricing in EUR and the official link.
Installing Ollama on an Apple Silicon Mac is as simple as running one Homebrew command. Then pick a model based on available RAM (Phi-3 for 8 GB, Llama 3.1 8B for 16 GB) and expose the local, OpenAI-compatible HTTP API on port 11434 to plug it into your own applications.
7 min1.3K4.1
We use first- and third-party cookies to analyze site traffic. You can accept them, reject them, or configure your choice.
Learn more about cookies
Cookie preferences
NecessaryEssential for the site to work. Always on.
AnalyticsHelp us understand how the site is used (Google Analytics).