
What is a vector embedding and what is it used for
About this video
Embeddings before the LLM: similarity sorts almost every document, and the model only decides the borderline ones.
A vector embedding is a list of real numbers that represents the semantic meaning of a piece of text, an image, or any other data. Two sentences with the same meaning produce vectors that are close together; two unrelated ones produce vectors that are far apart. Semantic search, RAG, and recommendation systems are all built on this principle.
Video transcript
- 0:01 Keyword matching fails:
- 0:02 it fires on any page that mentions the word.
- 0:05 Precision, 0.71.
- 0:08 Instead, embed all 36 documents:
- 0:10 one vector each, with no model calls.
- 0:13 By similarity to the topic, relevant pages and decoys pull apart on their own.
- 0:18 A floor of 0.15 rejects 19 documents and a ceiling of
- 0:23 0.40 accepts 6, for free.
- 0:27 Only the 11 uncertain ones reach the local LLM, the only expensive step.
- 0:32 Precision rises from 0.71 to 1.00.
More videos
Explainer
Firecrawl: Web Data for Agents
If you write your own crawler: robots.txt, one queue per host and 304 Not Modified make the polite option the cheap one too.
Explainer
How to Install SearXNG with Docker
One use for your own instance: an AI agent that finds its own sources by querying SearXNG, without paying per search.
Explainer
The Computational Graph and Automatic Differentiation
The computational graph and automatic differentiation, in action.
Explainer
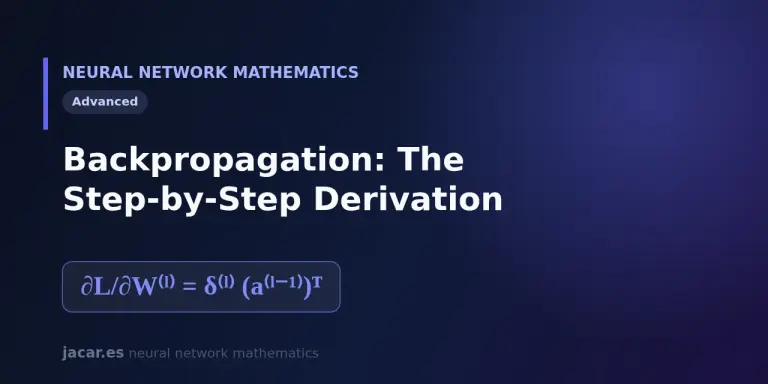
Backpropagation: The Step-by-Step Derivation
The backpropagation derivation, factor by factor with the chain rule.